Doc2Box
Recover human-aligned OCR text blocks.
69.1 AP
YOLOv12-X
arXiv:2608.04424August 2026
Grounded and Efficient Document Reasoning
We turn document regions into reusable visual evidence—connecting geometry, semantics, and reasoning so models can show not only what they know, but where that knowledge comes from.
01 · ADOPD 2026
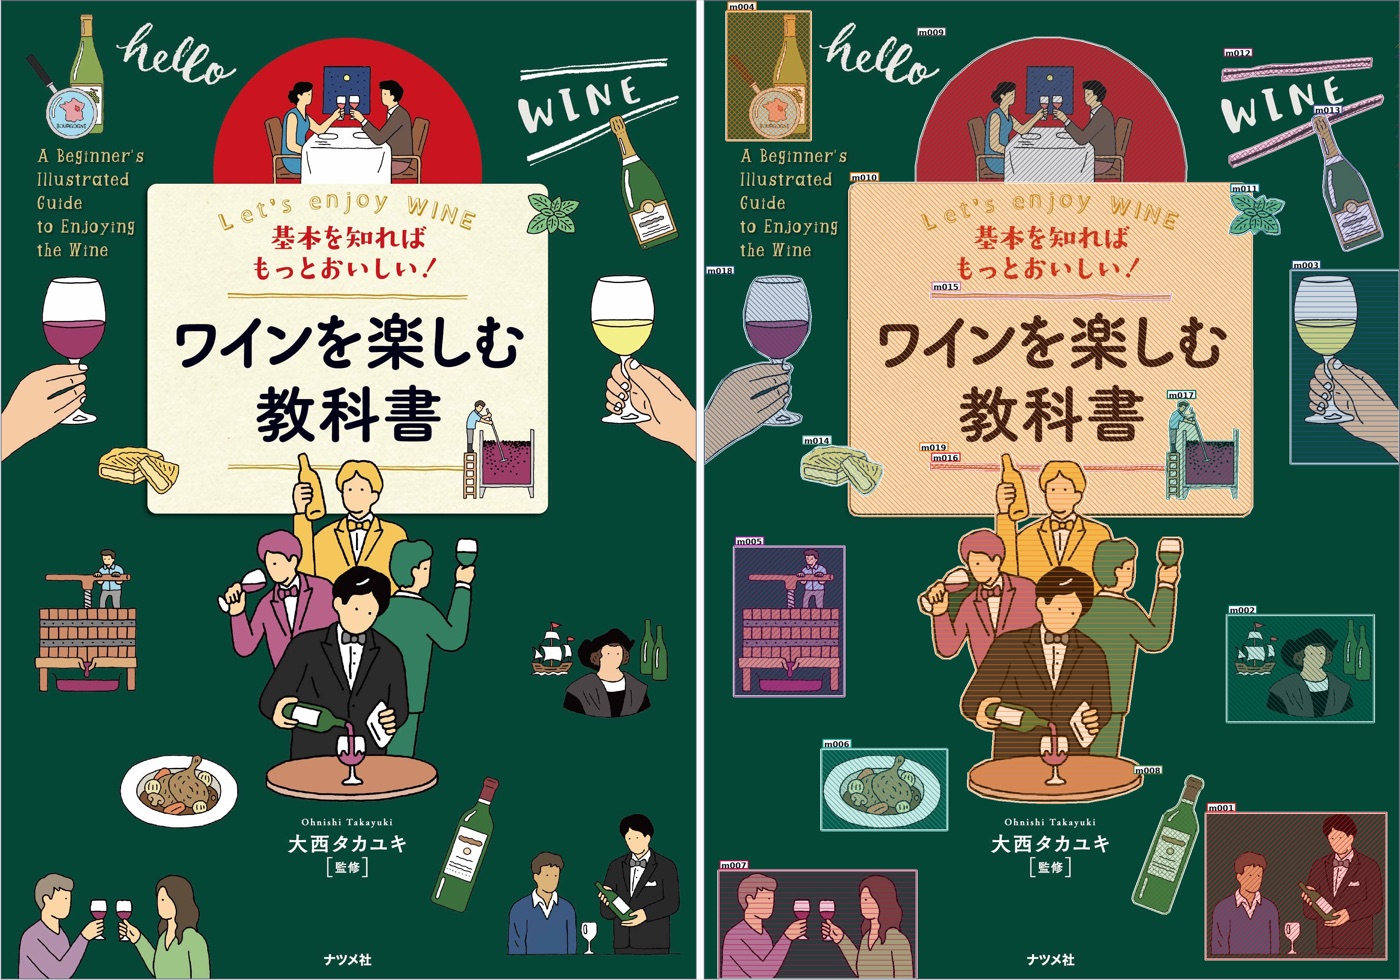
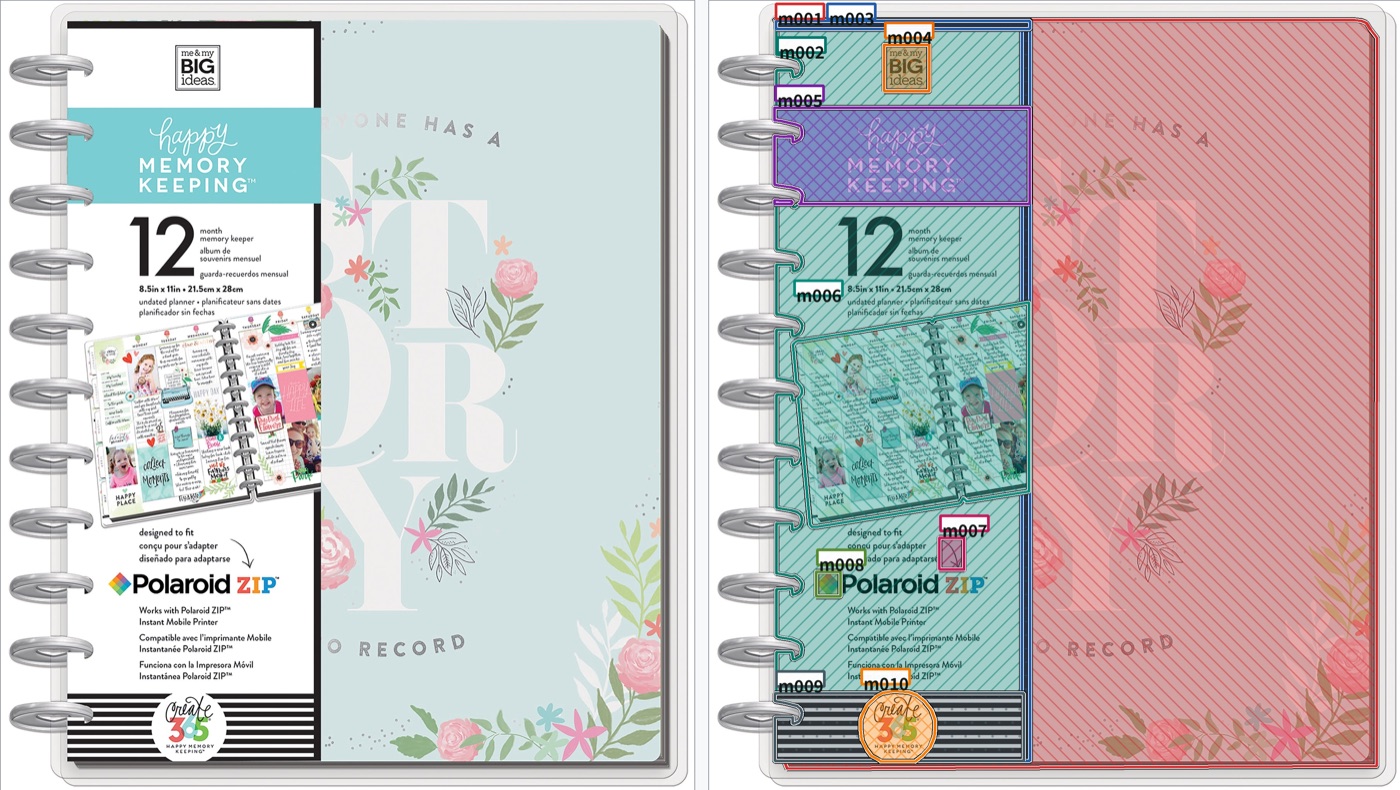
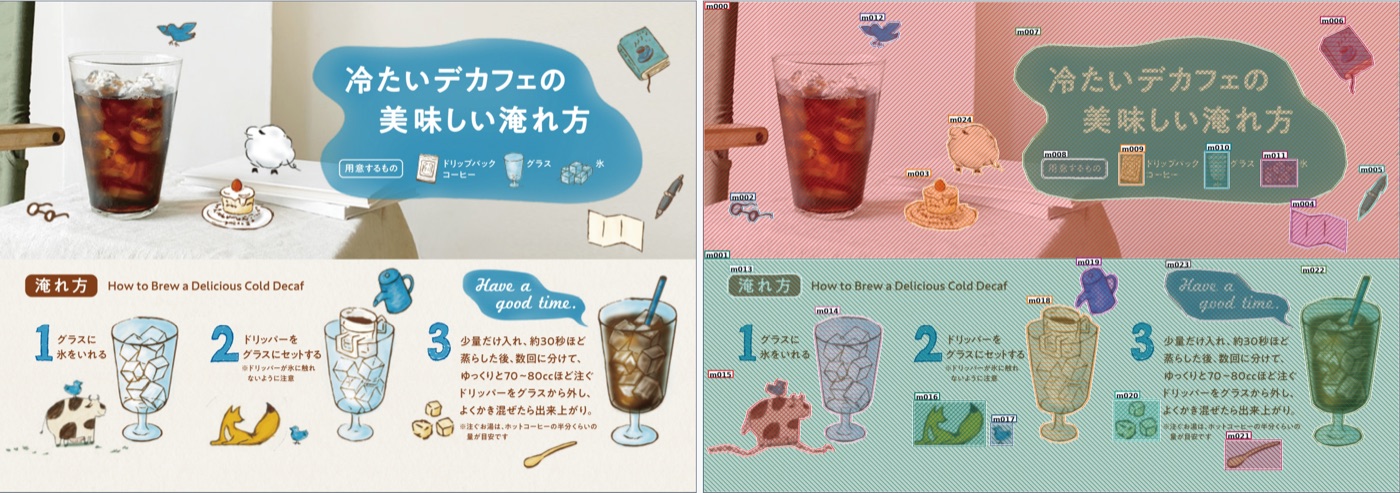
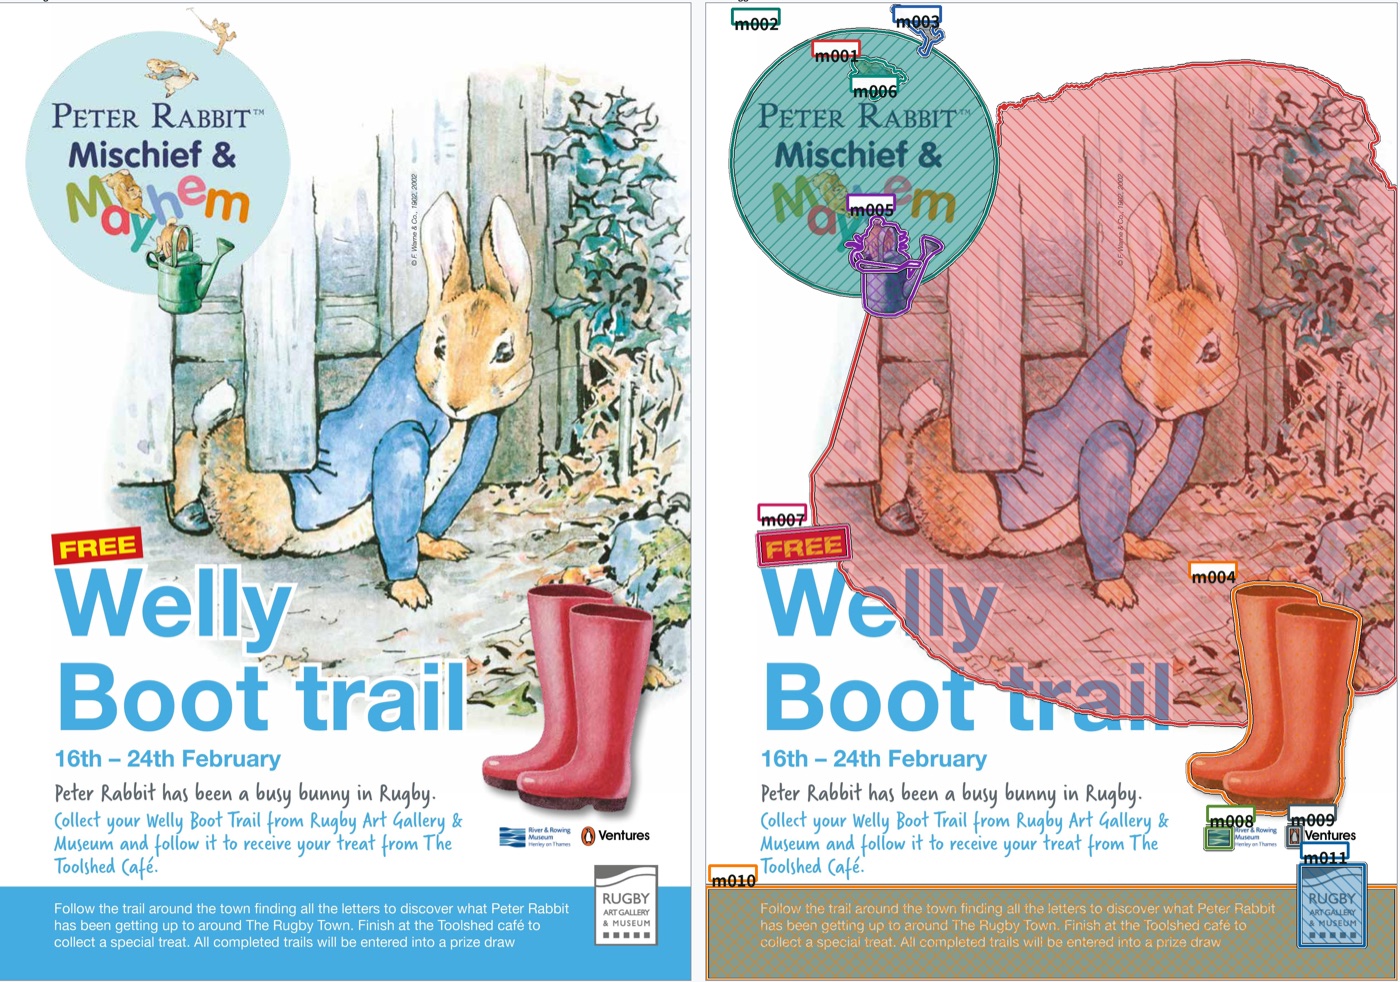
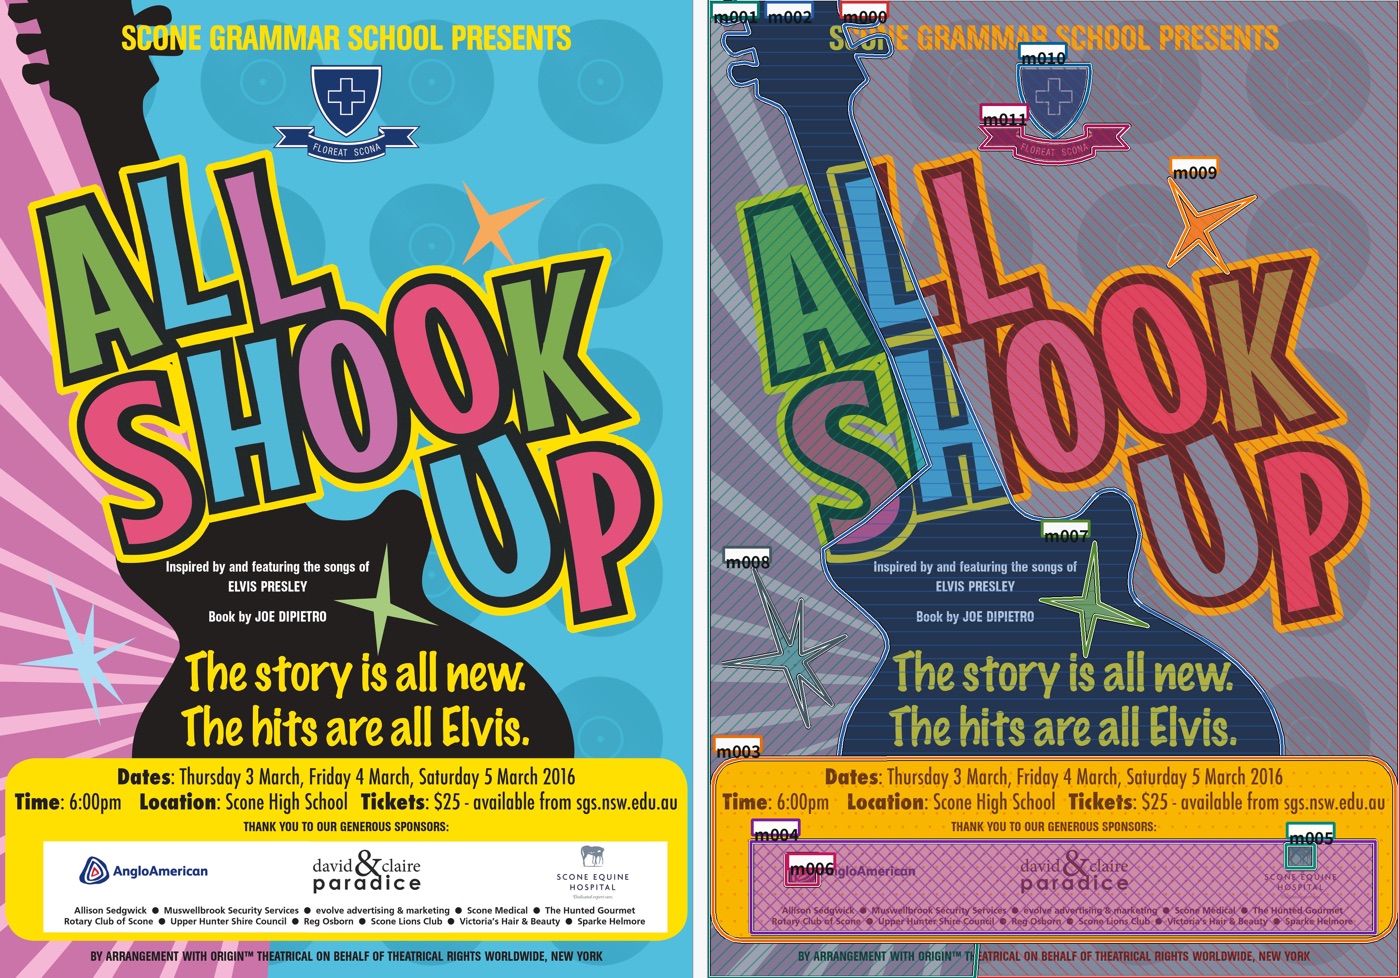
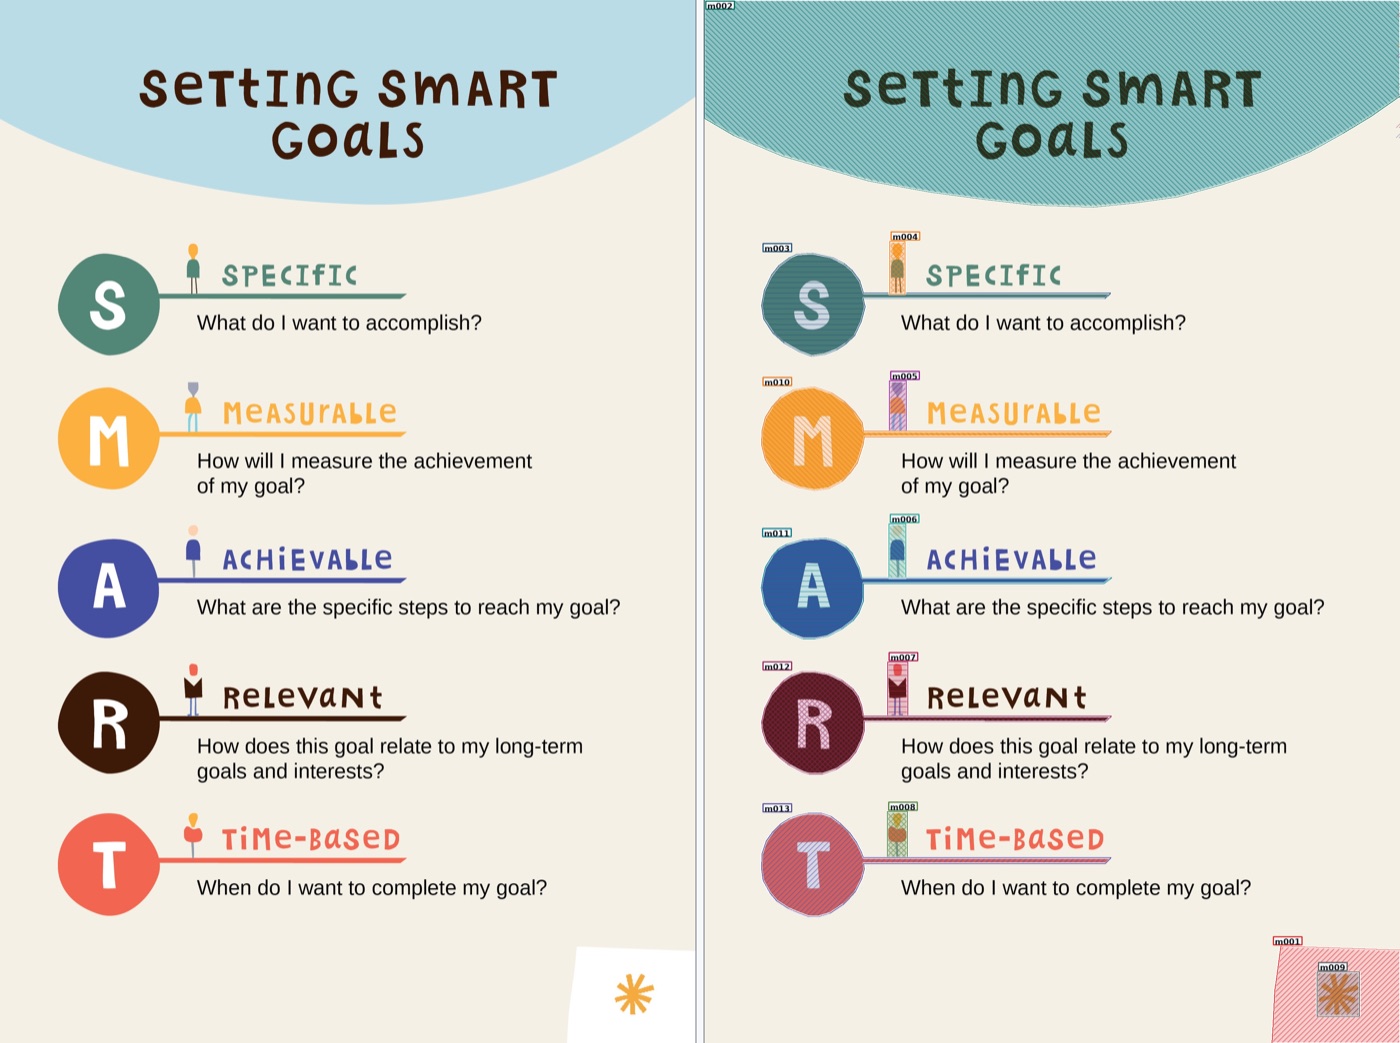
Traditional document understanding often stops at locating page elements. Thinking with Anchors treats every meaningful region as a grounded unit that a reasoning system can reference, compose, and verify.
Recover human-aligned OCR text blocks.
Segment visual entities with native polygons in a tag-agnostic setting.
Infer document-specific semantic roles.
Best fine-tuned result shown for each task
02 · DocCount benchmark
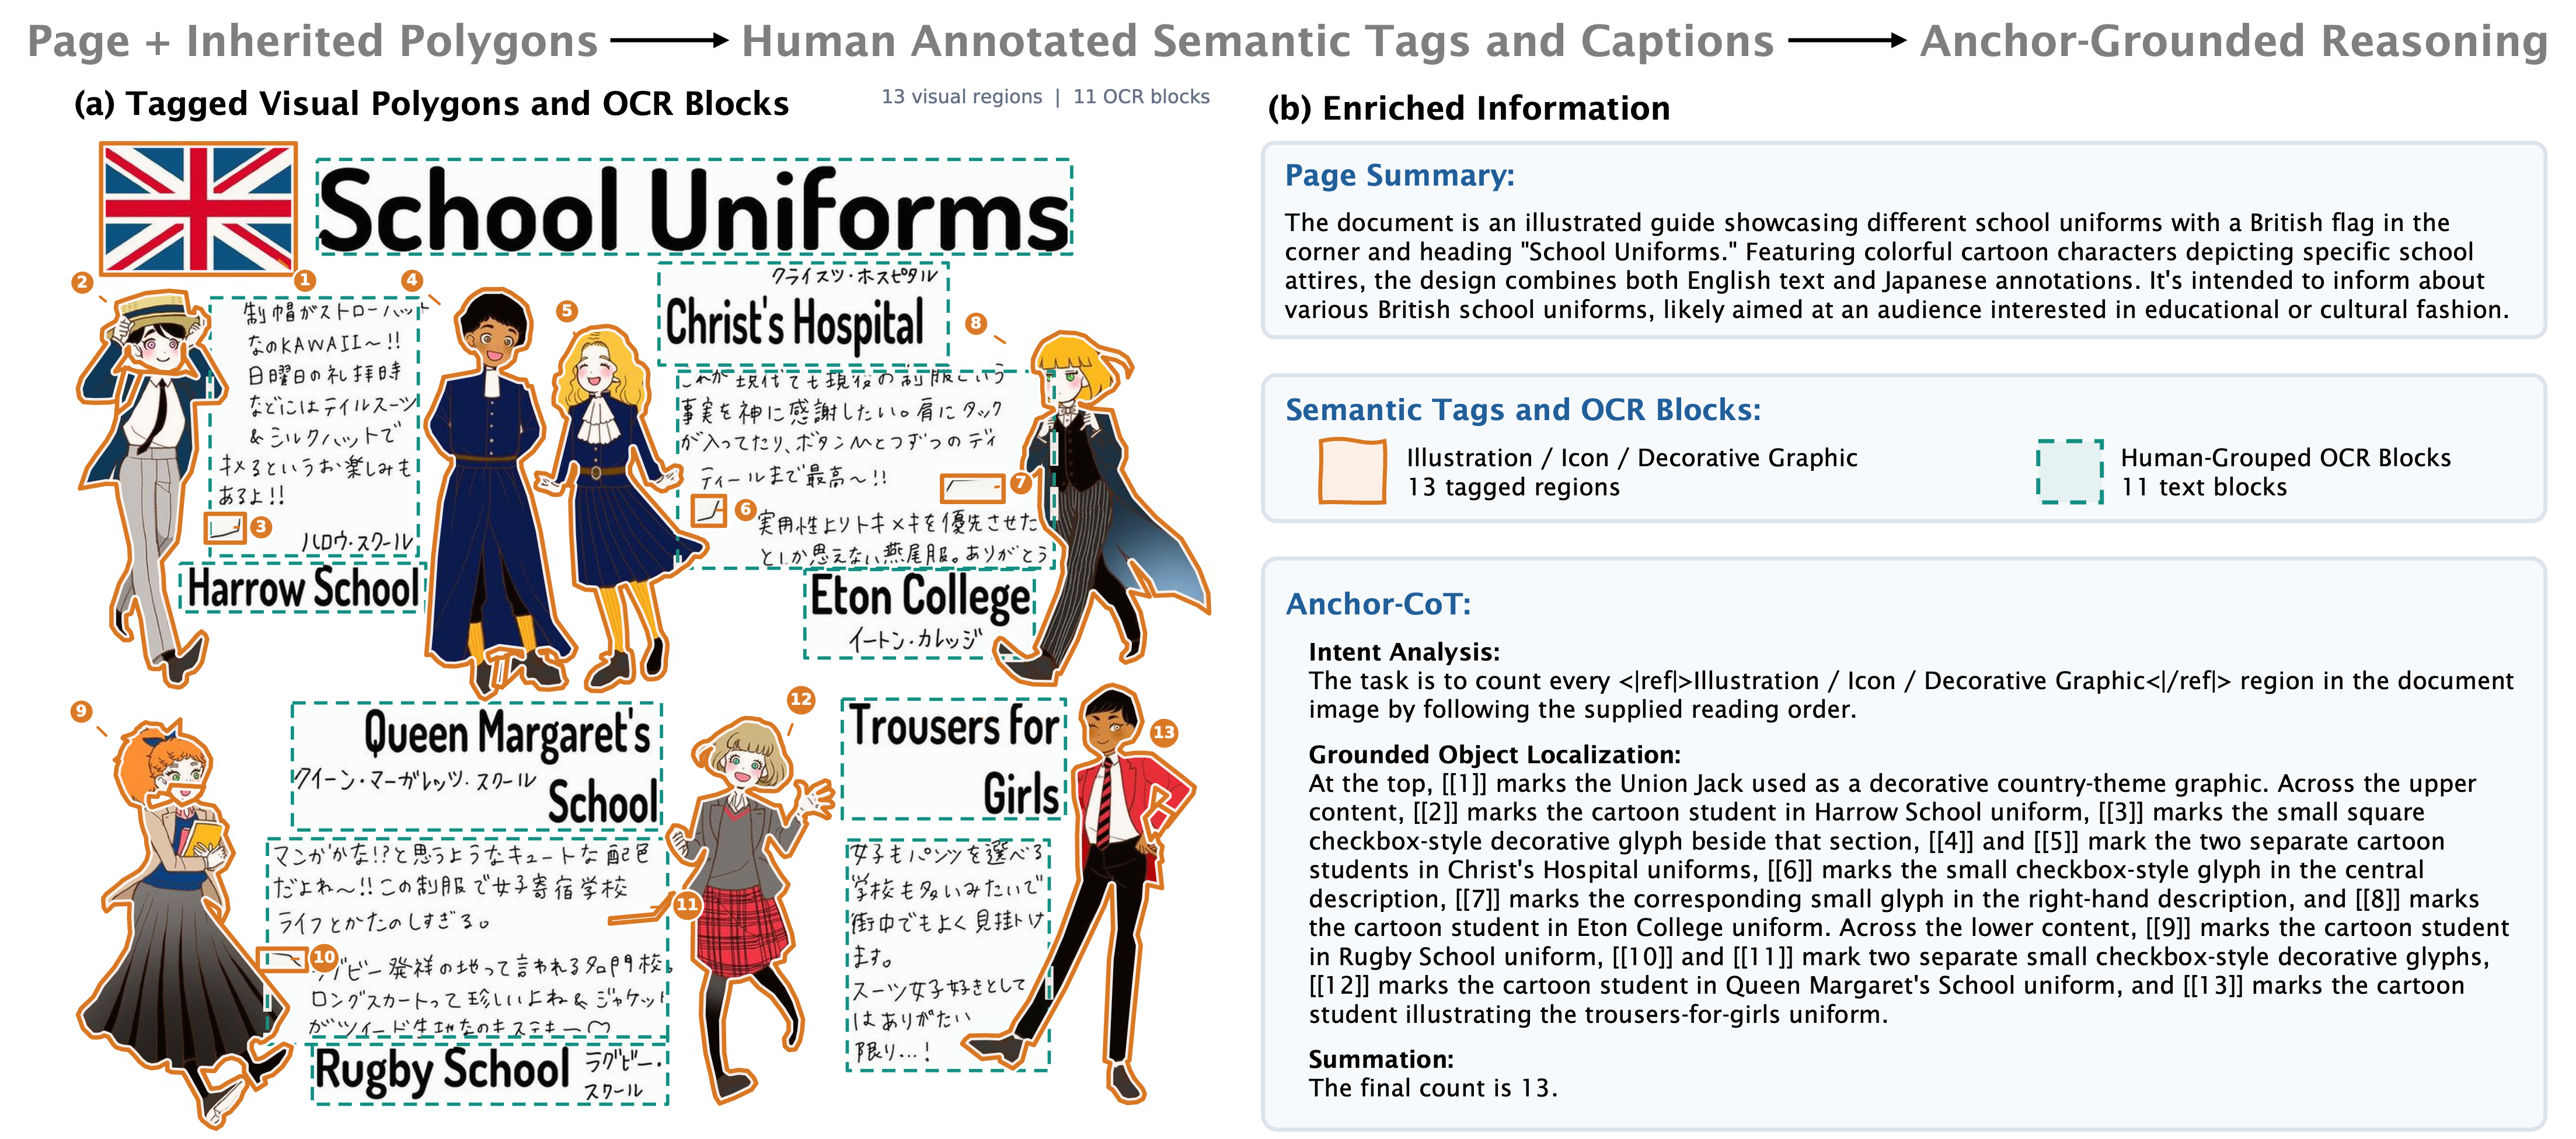
DocCount tests whether models can apply explicit semantic definitions, ground every qualifying region, and produce a verifiable count on dense document pages.
02 · DocCount benchmark
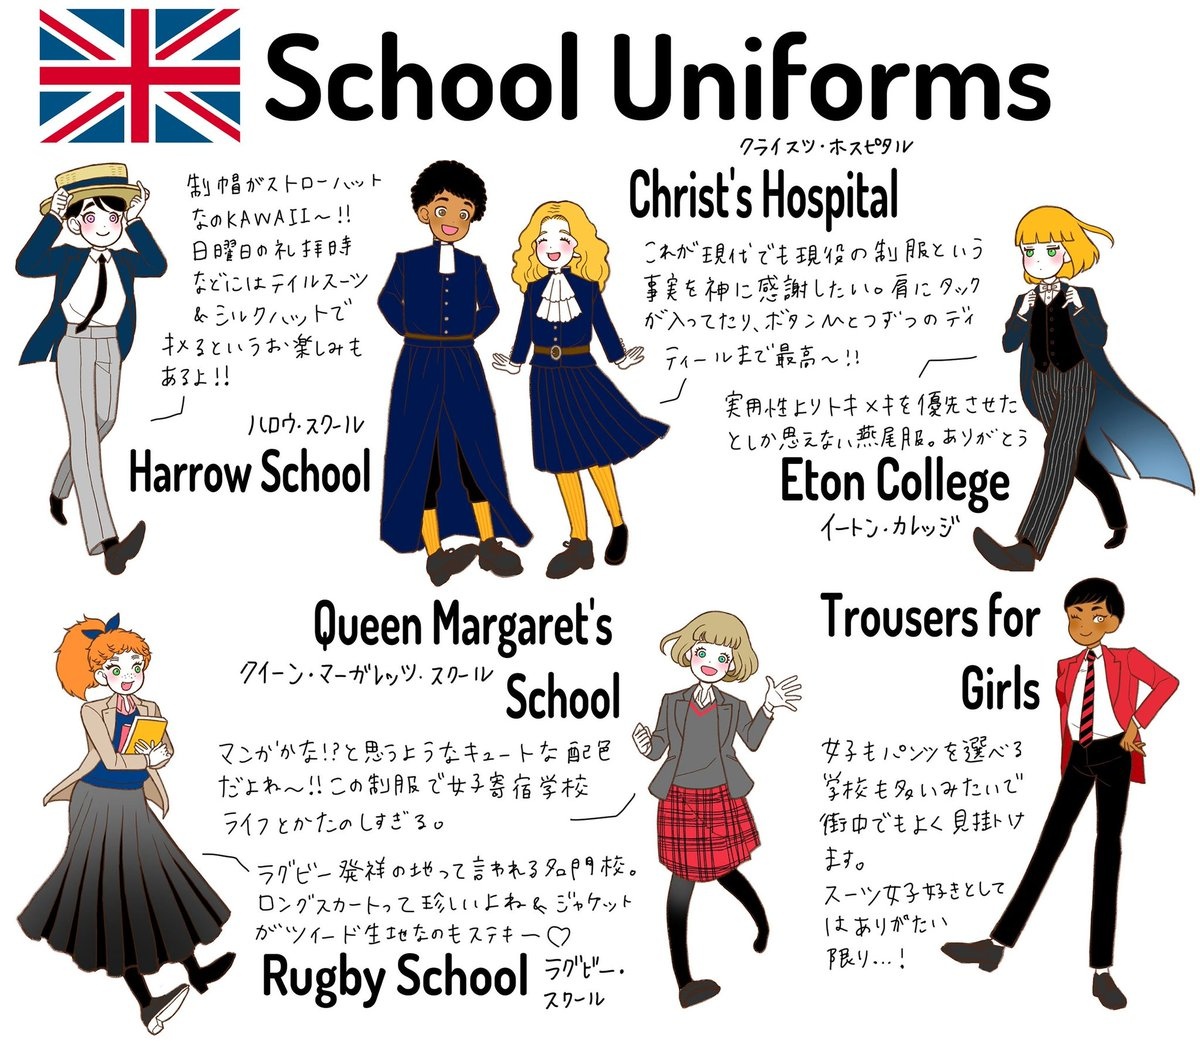
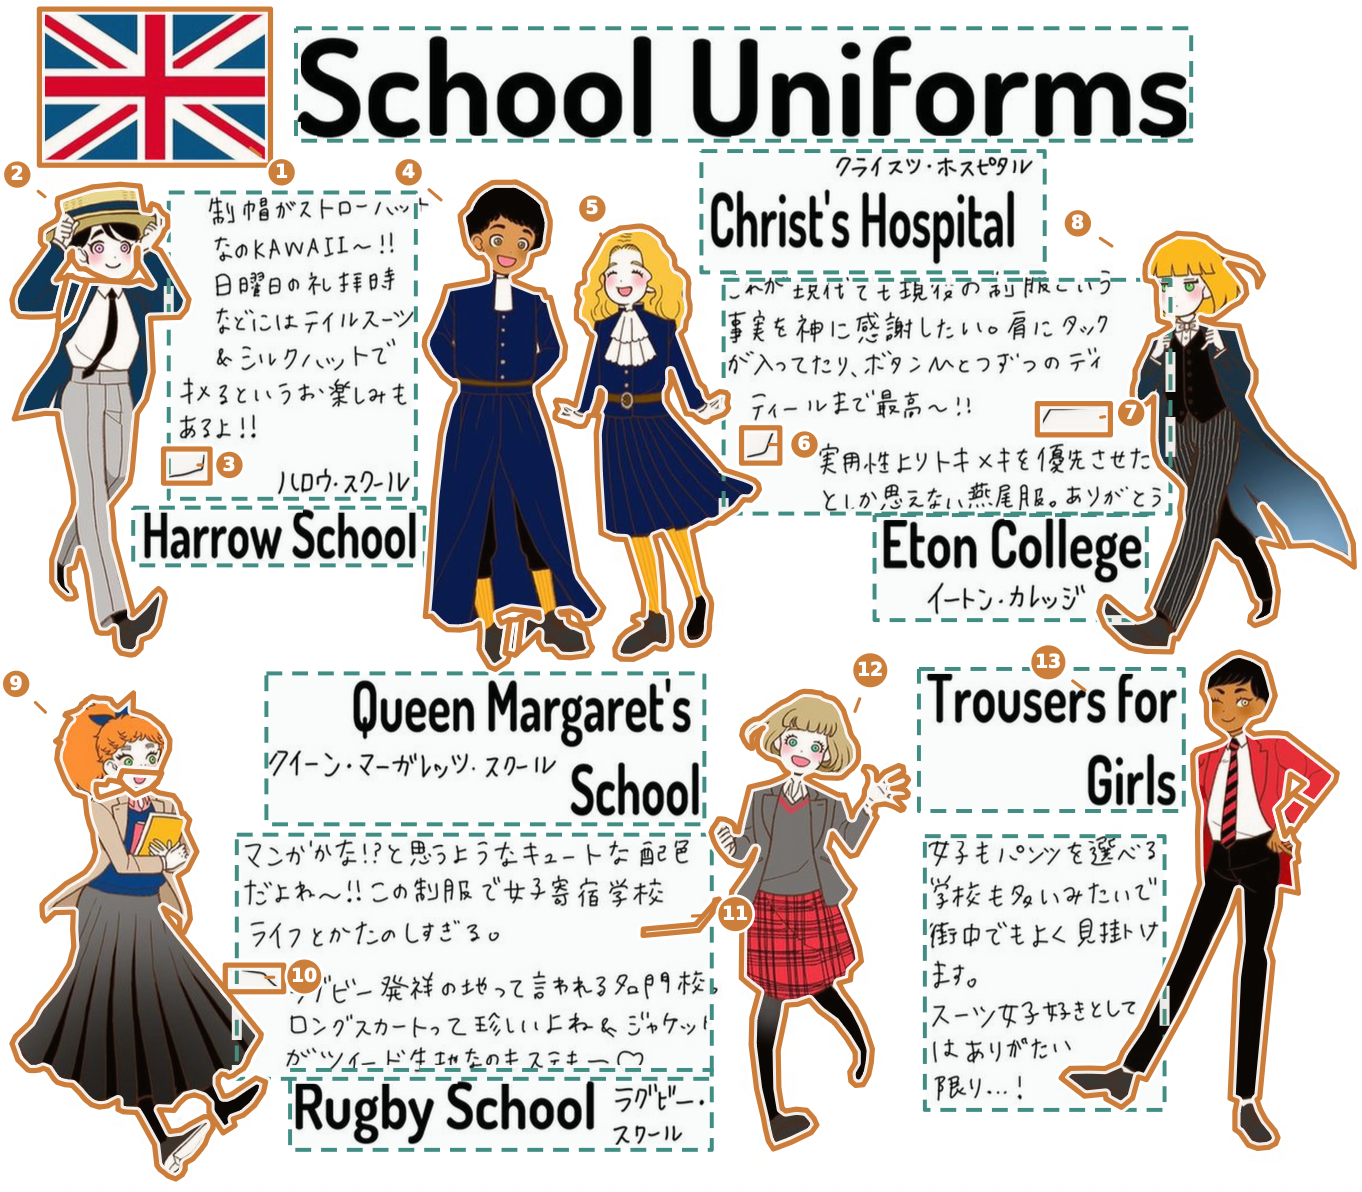
DocCount tests semantic counting in real document images. Every class is defined by inclusion, exclusion, and counting rules. Every answer is backed by polygon-level ground truth.
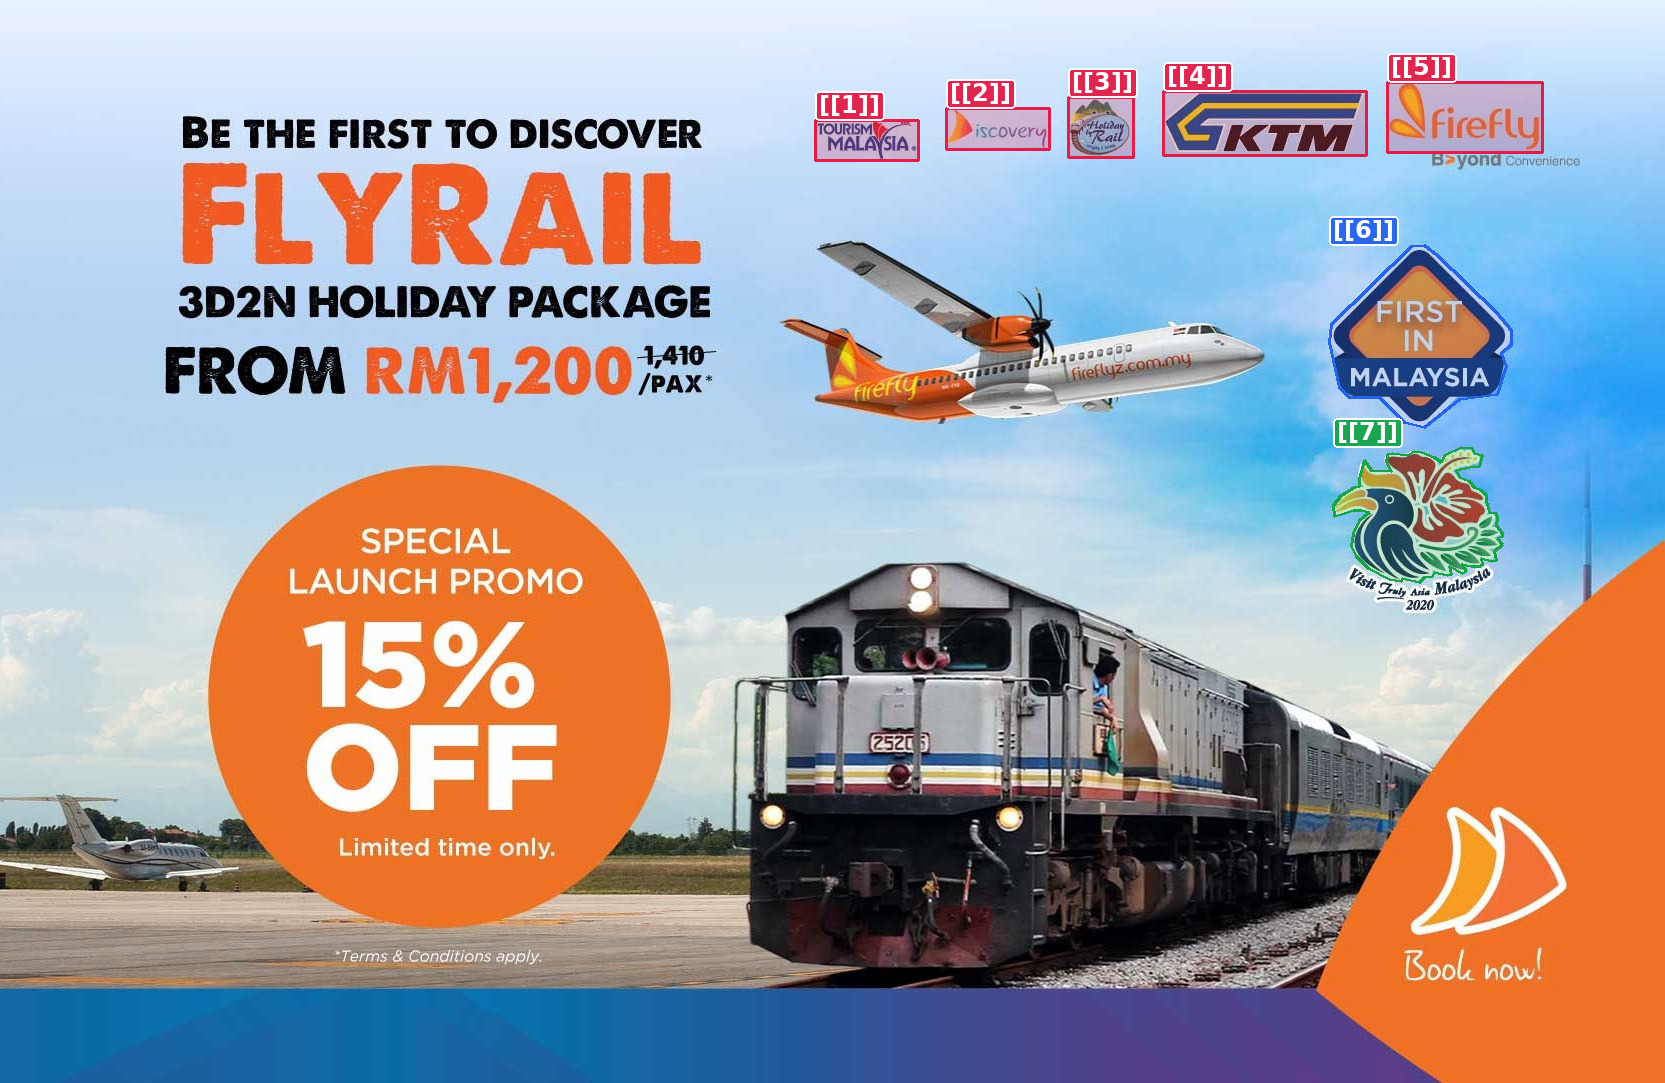
 Target class · Brand Logo
Interpret the definition
Count distinct standalone brand marks. Exclude decorative typography and product imagery.
Ground the candidates
Anchors [[1]] through [[7]] each identify a qualifying logo region.
Verify and answer
No anchor is duplicated or excluded by the grouping rule.
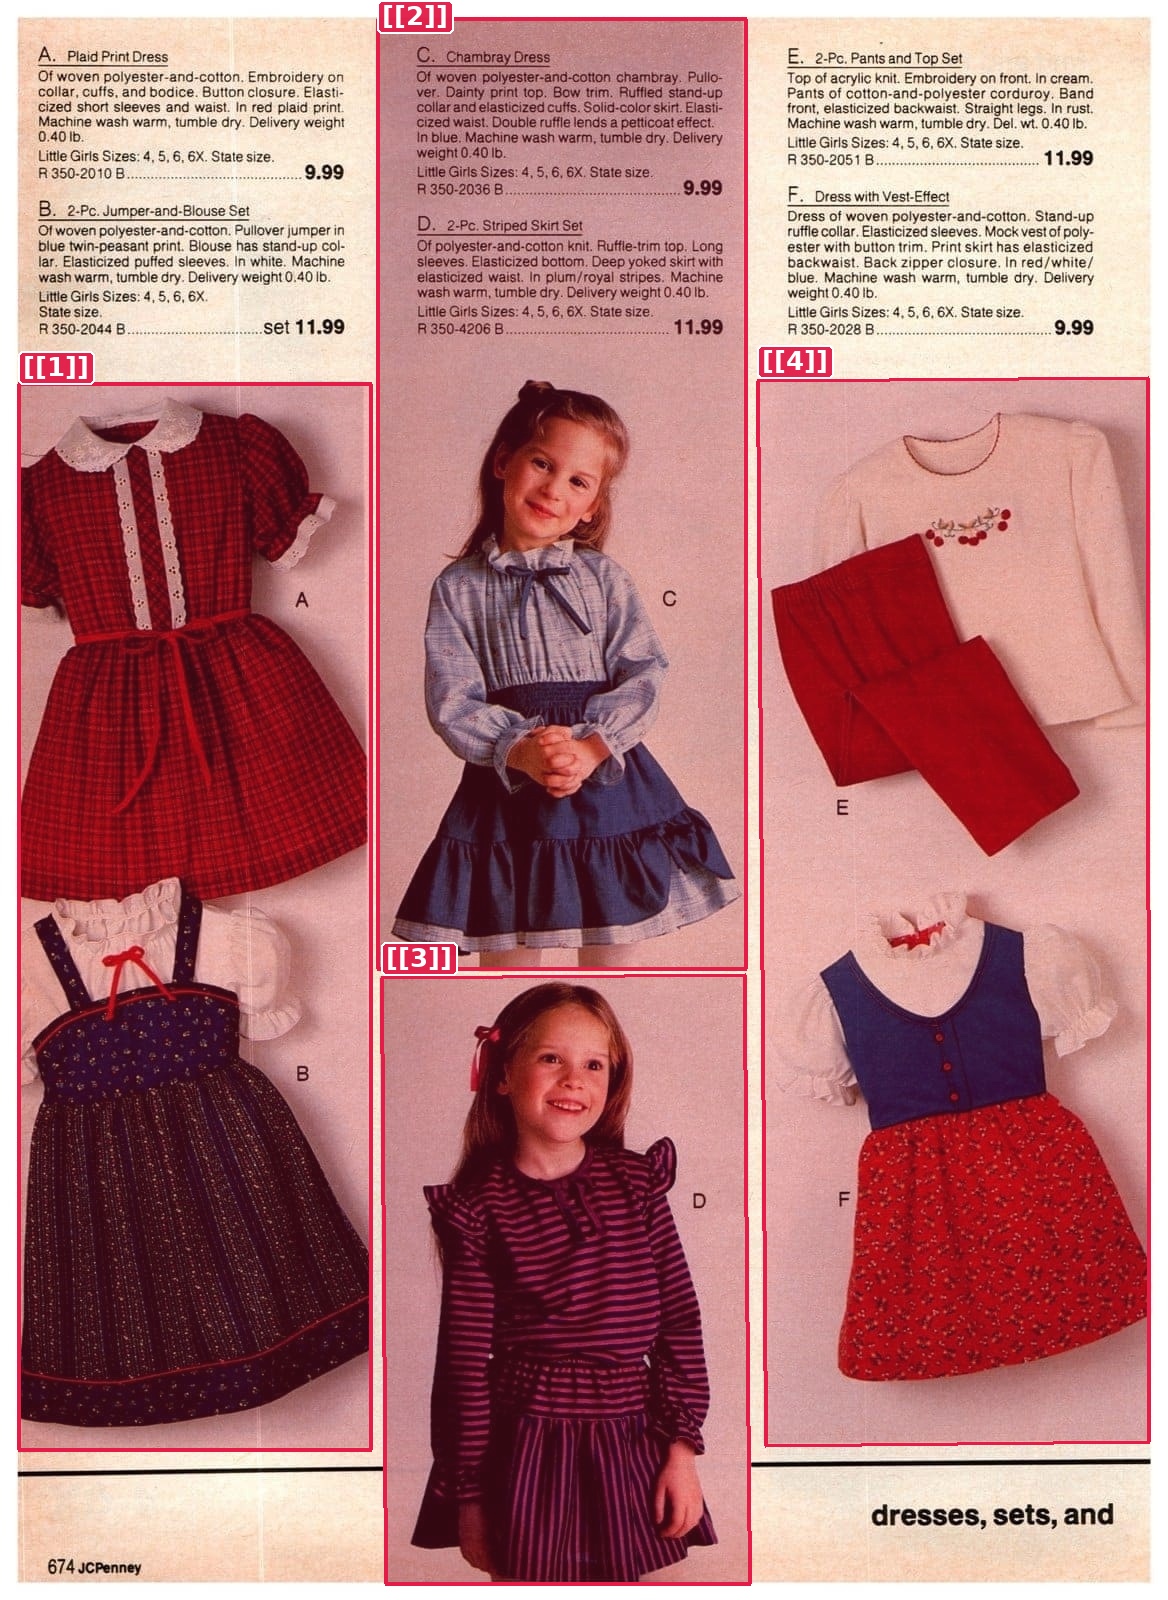
 Target class · Photograph
Interpret the definition
Count distinct photographic regions. Group subjects that share one photograph; exclude catalog text and flat graphics.
Ground the candidates
Anchors [[1]] through [[4]] identify the four qualifying photograph regions.
Verify and answer
Each counted region is visually distinct, and no catalog text is included.
DocCount results
Results use exact integer accuracy over all 442 questions.
Reproduce the evaluation